Google E-E-A-T: The Complete B2B Content Framework
What You’ll Learn in This E-E-A-T Whitepaper
Google has not revised E-E-A-T since December 2022. The framework held steady through two AI search documentation launches, and Google’s own AI optimization guide never uses the term. Most of the E-E-A-T guidance still in circulation describes a version of the framework Google has already replaced.
This paper works from the primary record. It runs from the December 2022 announcement that added Experience through to the AI optimization guide updated on 10 July 2026, and every claim in it carries a date and a link. It covers what raters are told to look for, where the review standard rises on Your Money or Your Life topics, which signals correlate with citation in AI answers, and how to score a single page in twelve questions.
The framework in this paper rests on research we ran and published, and these are the findings that shape it:
- 497 pages scored on twelve content signals: author bylines showed no independent effect on AI citation once content type and site authority were accounted for
- 97 percent of Your Money or Your Life queries: zero citations came back from ChatGPT across six weeks of tracking
- 57.8 percent of editorial pages cited against 25 percent of landing pages: the shape of a page carries further than the name on it
Figures drawn from The AI Content Fingerprint and The AI Visibility Gap, both published by Digital Authority Partners in 2026. Every source in the paper is dated and linked.
Six Things This Guide Will Help Your Content Team Do

1. Date-check the E-E-A-T guidance on your roadmap
The paper opens on a timeline of seven dated events, from the December 2022 rewrite that added Experience to the AI optimization guide updated on 10 July 2026. Run your current guidance against it. Advice that carries no date usually describes a version of the framework Google has since moved on from.

2. Score a page in twelve questions
The paper closes with a working diagnostic: twelve questions, two points each, twenty-four at the top. Purpose, byline, first-hand evidence, source dates, ownership and third-party coverage all carry the same weight. Four score bands tell you which items pay next, so a rewrite starts from evidence.

3. Set the review standard by YMYL position
Google rewrote Your Money or Your Life in December 2022 into four harm categories on a spectrum, and much guidance still repeats the older seven-industry list. You get the current definition, the wording raters work from, and a way to score each content type once so the review bar matches it.

4. Fund the signals that correlate with AI citation
Across 75,000 brands measured, off-site mentions track AI visibility more closely than any on-site metric. Brands in the top quarter for web mentions averaged 169 AI Overview mentions against 14 for the quarter below. The paper shows which layer of a content programme earns that coverage.

5. Redirect three line items in next year’s budget
Schema for AI visibility, llms.txt files and date-only refreshes appear on most 2025 content roadmaps. Google or a controlled study has since answered all three, and the paper cites each answer with its date. That frees budget for the layer that carries citation.
6. Brief writers on the specifics only a practitioner holds
Experience asks what Expertise cannot answer: actual use of a product, a place visited, a case handled. Google’s 2026 restatement calls this non-commodity content. You get the rater wording, the test raters apply, and the brief lines that get first-hand detail out of a subject expert and onto the page.
Peek Inside the Guide
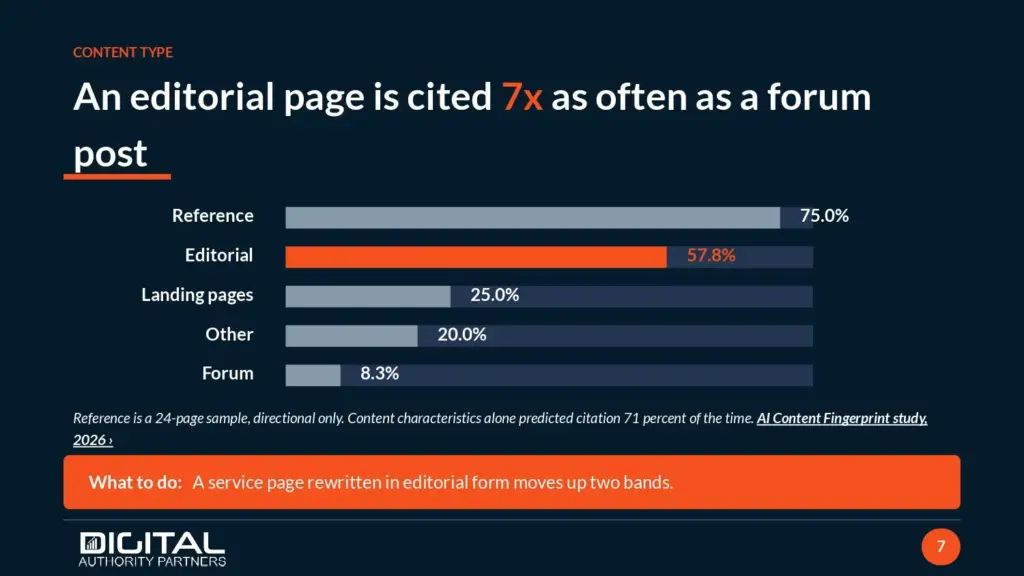
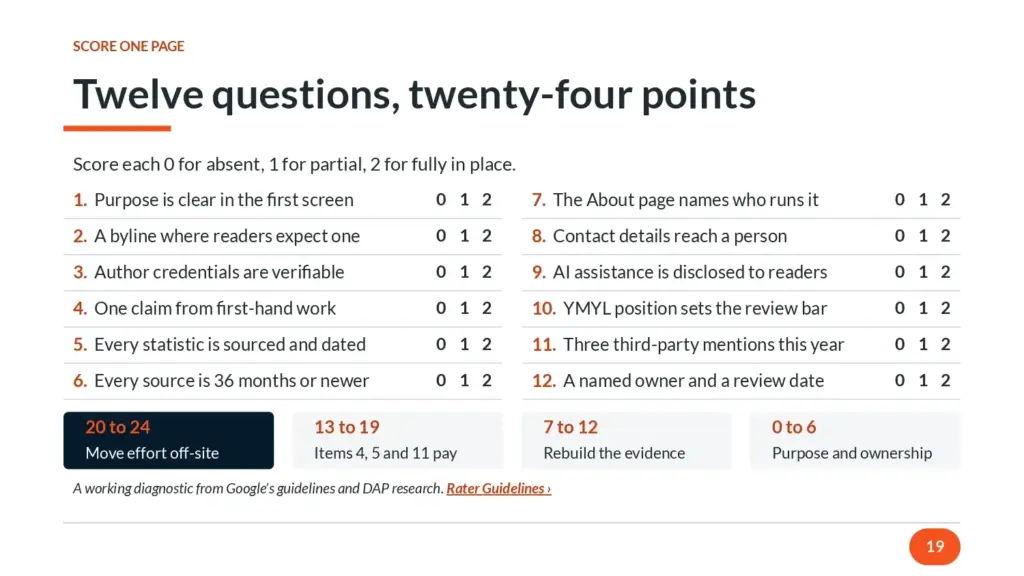
Table of contents
Why a framework Google last revised in 2022 still governs, and what the AI guides changed
Seven dated events, from the December 2022 rewrite to June 2026
497 pages, twelve signals, and what bylines moved
Our research, Google on the record, and an outside analysis of health citations
The content-type ladder, from reference pages down to forum posts
What Experience asks, in Google’s 2022 wording and its 2026 restatement
Rater guidelines section 3.4, and the three places trust gets read
Four harm categories on a spectrum, and how to score your own content types
Where citations thinned out, and why one measurement wave falls short
How ChatGPT and Google AI Overviews invert each other by source type
What correlates with AI visibility, and three line items the studies have answered
Twelve questions, six operating layers, and published client results
Similar white papers
Google treats financial queries differently from every other vertical. The same system that writes confident overviews for recipes and travel applies stricter safety filters to...
The Department of Justice moved the first Title II compliance date to 26 April 2027, which leaves eight months for public entities serving 50,000 people...
Most software evaluations finish somewhere a vendor does not control. 6sense measured 94% of buying groups ranking their vendors before speaking to a seller, with...
Have questions about this white paper?
Let’s talk!